Search News
Industry Portal
Popular Tags
What makes a technical product comparison platform reliable?
Author
Time
Click Count
A reliable technical product comparison platform makes its evidence inspectable. Side-by-side values are useful only when they retain the conditions that produced them: test configuration, source document, revision date, unit convention, interface assumptions, and known exclusions. Without that context, a comparison can look precise while directing selection toward equipment that performs well only in a narrow or incompatible operating envelope.
This distinction matters when a product affects safe train separation, current collection at high speed, braking distance under repeated duty, cargo containment integrity, or vessel routing availability. A figure such as peak current, stopping capability, boil-off performance, or communications latency has no stable meaning on its own. The platform becomes reliable when it preserves the engineering relationship between that figure and the physical, environmental, and operational conditions behind it.
Traceable data rather than polished specifications
The first test is whether every consequential claim can be traced to a source and a version. A reliable entry identifies whether a value comes from a manufacturer datasheet, a controlled drawing, a type-test record, an installation manual, a class-related technical document, or an independently published reference. It should also distinguish a declared design value from a demonstrated test result and from a calculated estimate.
Revision control is particularly important for equipment with long qualification and delivery cycles. A comparison assembled from an older traction converter datasheet and a newer cooling-system manual may silently combine different hardware revisions. Likewise, a vessel system description can remain broadly accurate after a sensor, valve arrangement, software release, or containment detail has changed. Good comparison intelligence records the document issue, release date where available, and the precise configuration to which a claim applies.
Units need similar discipline. Converting pressure, temperature, force, power, energy consumption, signal timing, or vessel capacity is simple arithmetic; interpreting the converted result is not. Values should retain their original unit and show the conversion method where unit choice could affect a threshold or tolerance. A nominal voltage without its permitted operating range, for example, cannot establish electrical compatibility. A speed rating without contact-wire geometry, aerodynamic exposure, or duty duration cannot establish pantograph suitability.
Comparable does not mean merely similar
Many weak comparisons place adjacent products in the same category because their names or headline functions resemble each other. Engineering comparability requires a shared basis of comparison. Before ranking alternatives, the platform should establish whether the products serve the same system boundary, interface level, and operating duty.
A rail braking assembly may be compared at the friction-material level, the caliper level, the bogie integration level, or the train-control level. These are related but not interchangeable. Composite brake-pad performance depends on disc material, pressure profile, thermal history, moisture, wheel-slide protection behavior, and the energy absorbed across a braking event. Comparing a pad coefficient alone can conceal thermal fade, uneven wear, noise behavior, or a change in stopping consistency after repeated high-energy applications.
The same problem appears in railway signalling. Two interlocking-related products may both support a stated safety architecture, yet differ in route capacity, communication topology, diagnostic coverage, maintenance access, input/output behavior, redundancy design, or interface responsibility. A platform that labels both as equivalent because they share a safety claim creates a false comparison. The relevant question is whether each component fits the same operational design and failure-management strategy.
For smart container ships, an advertised digital capability may refer to onboard condition monitoring, shore-side optimization, a navigation support function, or an integrated fleet-management workflow. Treating those layers as a single feature exaggerates interchangeability. The comparison must state what is sensed, where data is processed, which decisions remain local, what communications path is assumed, and how the function behaves when connectivity is degraded.
Operating envelopes change the result
Reliable comparison records the boundary conditions that turn a nominal product characteristic into a usable selection criterion. Environmental loads, installation geometry, duty cycle, maintenance access, electrical quality, vibration, salt exposure, and failure consequences often change the order of preference.
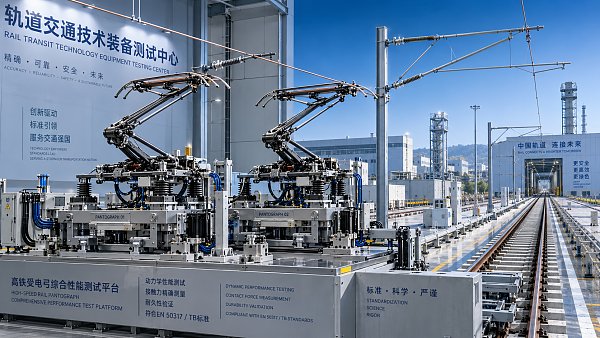
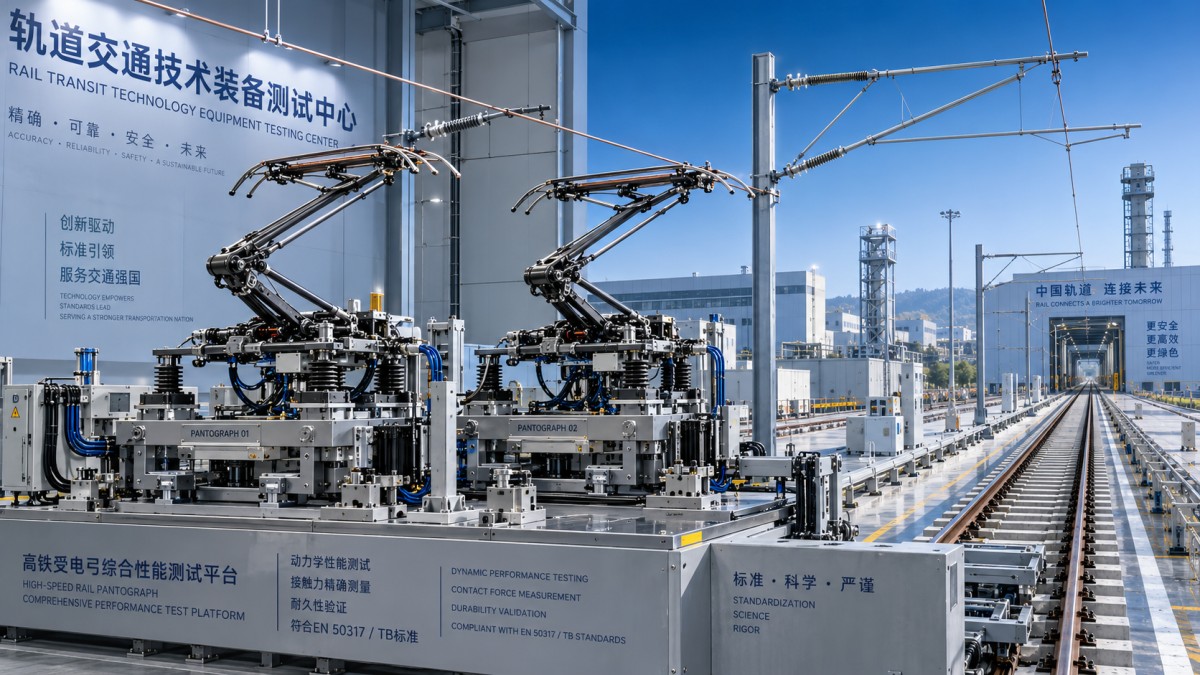
Consider a pantograph rated for a particular top speed. That value may have been established under a defined contact-line arrangement and a controlled aerodynamic condition. Roof equipment nearby, tunnel pressure effects, crosswinds, carbon-strip wear, and variations in overhead-line stiffness can alter contact quality. The highest published speed is therefore less informative than the evidence showing stable current collection within the actual route and vehicle configuration.
For cryogenic cargo systems, insulation performance cannot be separated from the whole containment arrangement. Heat ingress is influenced by material selection, fabrication quality, joints, supports, local stress concentration, tank movement, and the cargo operating profile. Two systems described with similar insulation terminology can differ materially in inspection access, repair complexity, response to local damage, and the assumptions used to manage boil-off gas.
Methodology must be visible enough to challenge
Trust grows when the comparison method is explicit. A platform should explain how it decides that fields are equivalent, how it normalizes terminology, how it treats missing values, and whether it ranks products or only presents evidence. A blank field should not silently become a zero, a favorable assumption, or an indication that the feature is absent. It should remain visibly unverified or unavailable.
Definitions deserve more attention than ranking formulas. “Availability,” “efficiency,” “response time,” “capacity,” and “service life” are often calculated over different boundaries. One traction system efficiency statement may include the converter and motor losses but exclude auxiliaries and cooling demand; another may use a broader vehicle-level boundary. Neither is automatically misleading, but they cannot be ranked without restating the boundary.
A transparent methodology also separates hard filters from trade-offs. Interface voltage, mounting envelope, gauge, communication protocol, hazard classification, and required safety function are usually pass-or-fail conditions. Weight, diagnostic depth, maintainability, energy use, spare-part commonality, and lifecycle intervention frequency may be trade-offs once compatibility is established. Mixing both groups into a single score obscures why a technically attractive option cannot be deployed.
Where a score is used, its weighting should remain editable or at least disclosed. A configuration with restricted roof space may place a high penalty on mass and installation envelope. A route with frequent stops may weight thermal recovery and brake wear differently from a long-distance route. A vessel project with limited dry-dock access may elevate maintainability above a marginal difference in stated efficiency. A fixed universal ranking conceals these legitimate shifts in priority.
Interface evidence exposes hidden incompatibilities
Product comparisons often fail at interfaces rather than within the component itself. A reliable platform captures mechanical, electrical, software, hydraulic, pneumatic, thermal, and data interfaces in enough detail to identify where additional engineering work is likely.
For railway equipment, this includes mounting dimensions, mass distribution, cable entry, grounding arrangement, supply tolerance, connector families, electromagnetic compatibility assumptions, control signals, diagnostic access, and fallback behavior. An item that fits physically may still require a new harness, revised protective coordination, altered cooling flow, or changes to control logic. Those changes can affect commissioning scope and the evidence needed for system acceptance.
Marine comparisons need equivalent attention to piping interfaces, power distribution, fuel handling, control-system integration, space claim, drainage, ventilation, access routes, and classification-related design dependencies. A cargo-handling component that appears interchangeable on a process diagram may demand different valve sequencing, sensor locations, insulation transitions, or maintenance clearances in the actual vessel layout.
Interface claims should be categorized carefully. “Supports a protocol” is weaker than “has been documented with this message set, timing behavior, cybersecurity responsibility, and failure response.” “Compatible with an existing enclosure” is incomplete without ingress protection, heat dissipation, cable bend radius, grounding, vibration load, and access for inspection. A useful comparison makes the unknowns visible before they become late design changes.
Lifecycle evidence has to include degradation
Initial performance is rarely the whole selection question. Reliable records show how performance changes with age, contamination, cycling, temperature, corrosion, vibration, fatigue, and maintenance intervention. A component can meet its initial specification while imposing frequent inspection, specialized tooling, difficult removal, or narrow adjustment tolerances over its service life.
Wear mechanisms should be described at the level that affects selection. Carbon contact strips wear differently when contact-wire condition, current density, arcing, weather, and uplift behavior change. Brake materials should not be assessed only by their first-stop friction level when repeated thermal cycling, disc compatibility, particulate generation, and wet performance affect fleet behavior. In a marine setting, salt-laden air, condensation, coating condition, inaccessible fasteners, and cyclic motion can determine whether a nominally robust subsystem remains serviceable.
Maintenance intervals are meaningful only when the trigger is known. Calendar-based intervals, accumulated operating hours, mileage, switching cycles, sensor alarms, and inspection findings are not equivalent triggers. A comparison should state the inspection basis, the replacement threshold where published, and whether access requires equipment isolation, tank preparation, vessel downtime, or removal of adjacent assemblies.
Contradictions are evidence, not noise
When documents disagree, the reliable response is not to select the most favorable number. The contradiction should remain visible with its likely cause: different revision, test temperature, equipment variant, measurement boundary, optional feature, software setting, or source quality. A resolved record should explain why one source has priority. An unresolved record should be marked as such.
This practice prevents a common failure in comparison tables: false certainty created by aggressive normalization. A product family may have several variants with distinct materials, cooling arrangements, enclosure ratings, propulsion modes, or sensor packages. Assigning one family-level value to every variant saves space but corrupts the comparison. Granularity should follow the decision boundary. When a variant affects fit, safety behavior, duty capability, or maintenance, it needs its own record.
Currency and governance determine whether trust lasts
Technical information ages unevenly. Dimensions and material specifications may remain stable for years, while software compatibility, communications support, component availability, service bulletins, and configuration rules can change much faster. A dependable platform shows when critical fields were last reviewed and distinguishes a source publication date from the date the entry was verified.
Governance also requires a defensible correction path. New evidence should be attributable, changes should preserve an audit trail, and editorial interpretation should remain separate from source facts. This is especially important where a comparative statement could affect safety justification, integration scope, maintenance planning, or long-lead equipment selection.
The most reliable comparison is therefore not the one with the largest specification table. It is the one that lets a claim be traced, tests equivalence before ranking, retains operating conditions, reveals interface gaps, and refuses to hide uncertainty behind a score. For complex rail and maritime equipment, that discipline turns product data into evidence that can withstand technical review.
Recommended News
 Oct 05, 2026How EN 45545 shapes material selection for railway safety systemsRailway safety systems EN 45545 guide explains how to select fire-safe materials, verify evidence, and reduce approval risk across rail vehicle assemblies.
 Oct 04, 2026What makes a technical product comparison platform reliable?Technical product comparison platform reliability starts with traceable data, operating context, interface evidence, and transparent methods. Learn what makes comparisons trustworthy.
 Oct 03, 2026What to verify before selecting ocean going vessels suppliersOcean going vessels suppliers: verify shipyard capability, compliance, fuel readiness, digital systems, quality control, delivery reliability, and after-sales support.
 Oct 02, 2026What should operators compare when sourcing high speed rail equipment in Europe?High speed rail equipment Europe sourcing guide: compare interoperability, safety evidence, lifecycle cost and supplier support to protect fleet availability.
 Sep 29, 2026What drives traction systems price differences between rail projects?Traction systems price differences explained: compare duty cycles, voltage compatibility, integration, localization, and lifecycle costs for smarter rail procurement.
 Sep 26, 2026What to assess before selecting an electric traction system manufacturerChoose an electric traction system manufacturer with confidence. Explore key criteria for performance, reliability, safety, integration, energy efficiency, and lifecycle support.
 Sep 25, 2026When do full digitalization systems justify the investment?Full digitalization systems: discover when rail and maritime operators can turn connected data into safer operations, higher availability, and measurable ROI.
 Sep 23, 2026What drives automatic train control systems cost on rail projects?Automatic train control systems cost depends on integration, migration, safety testing, communications, and lifecycle support. Explore the key budget drivers for rail projects.
 Sep 21, 2026How to assess an ocean going vessel builder’s delivery riskAssess an ocean going vessel builder’s delivery risk with proven checks for schedules, capacity, design maturity, critical equipment, quality, and project controls.
 Sep 20, 2026What drives rail safety technology costs over a project lifecycle?Rail safety technology cost goes beyond equipment—explore lifecycle drivers from integration and safety assurance to cybersecurity, commissioning, and obsolescence.
 Sep 16, 2026What to verify before choosing an advanced ocean-going vessels supplierAdvanced ocean-going vessels supplier checklist: verify design authority, build quality, digital systems, delivery reliability, and lifecycle support before you buy.
 Sep 15, 2026What rail safety technology best reduces level-crossing risks in Southeast Asia?Rail safety technology Southeast Asia: discover how fail-safe signalling, barriers, obstacle detection and remote monitoring reduce level-crossing risks.
 Sep 14, 2026How exporters can reduce customs delays in global trade logisticsGlobal trade logistics for exporters: reduce customs delays with accurate data, clearance-ready documents, early filing, and proactive exception management.
 Sep 13, 2026When do global transportation network systems reduce delivery delays?Global transportation network systems reduce delivery delays by improving rail-port-vessel coordination, real-time visibility, and proactive decisions across complex land-sea supply chains.
 Sep 09, 2026When should you choose a rail and maritime manufacturer with dual-sector capability?Rail and maritime manufacturer guide: learn when dual-sector capability reduces integration risk, improves lifecycle support, and strengthens rail-to-port operations.
 Sep 08, 2026What to verify before selecting a railway signalling equipment supplierRailway signalling equipment supplier checklist: verify safety evidence, integration, cybersecurity, delivery capability, and lifecycle support before award.
 Sep 07, 2026How to size a traction power transformer for railway load demandTraction power transformer sizing guide: model railway load demand, peak duty, voltage regulation, harmonics, and contingency capacity for reliable service.
 Sep 07, 2026How do customization options for industrial connectors affect lead times?Customization options for industrial connectors can impact lead times, cost, and compliance. Learn how to specify smarter for rail and marine projects.
 Sep 05, 2026What information should an industrial sourcing guide include?Industrial sourcing information procurement guide: evaluate suppliers, compliance, lifecycle costs, interfaces, and lead times for smarter rail and maritime purchasing decisions.
 Sep 01, 2026How to find reliable maritime tender information before biddingMaritime tender information: learn how to verify sources, define bid-ready scopes, check qualifications, and reduce risk before submitting competitive marine bids.
 Aug 30, 2026How to select railway automation equipment for depots with phased upgradesRailway automation equipment for depots: learn how to plan phased upgrades that improve safety, throughput, integration, and lifecycle control.
 Aug 27, 2026How industrial sourcing intelligence pricing data supports budget approvalIndustrial sourcing intelligence pricing data helps teams benchmark scope, assess supplier risk, and build defensible budget approvals for complex rail and maritime assets.
 Aug 26, 2026When does a marine fuel efficiency solution make financial sense in the Middle East?Marine fuel efficiency solution Middle East: learn when retrofit savings, compliance value, and vessel data align to deliver credible ROI and smarter shipping investment decisions.
 Aug 24, 2026When does maritime automation for tankers deliver a real payback?Maritime automation for tankers delivers real payback when it cuts fuel use, reduces cargo risk, and improves uptime. See how owners can time investment for stronger ROI.